Agent operations
Agent operations fleet
Six specialist agents run on a schedule. A reviewer reads what each one actually wrote, and every run lands in a log you can inspect.
858
runs logged
On 117 distinct days.
10 Jun – 5 Oct 2026
125
silent defects caught
Each came from a run that had reported success. A person sees the note before acting on the file.
28 Jul – 5 Oct 2026
≈ $0.03
median cost per run
Estimated from logged tokens on 129 runs. Not an invoice.
29 Aug – 5 Oct 2026
The actual tool
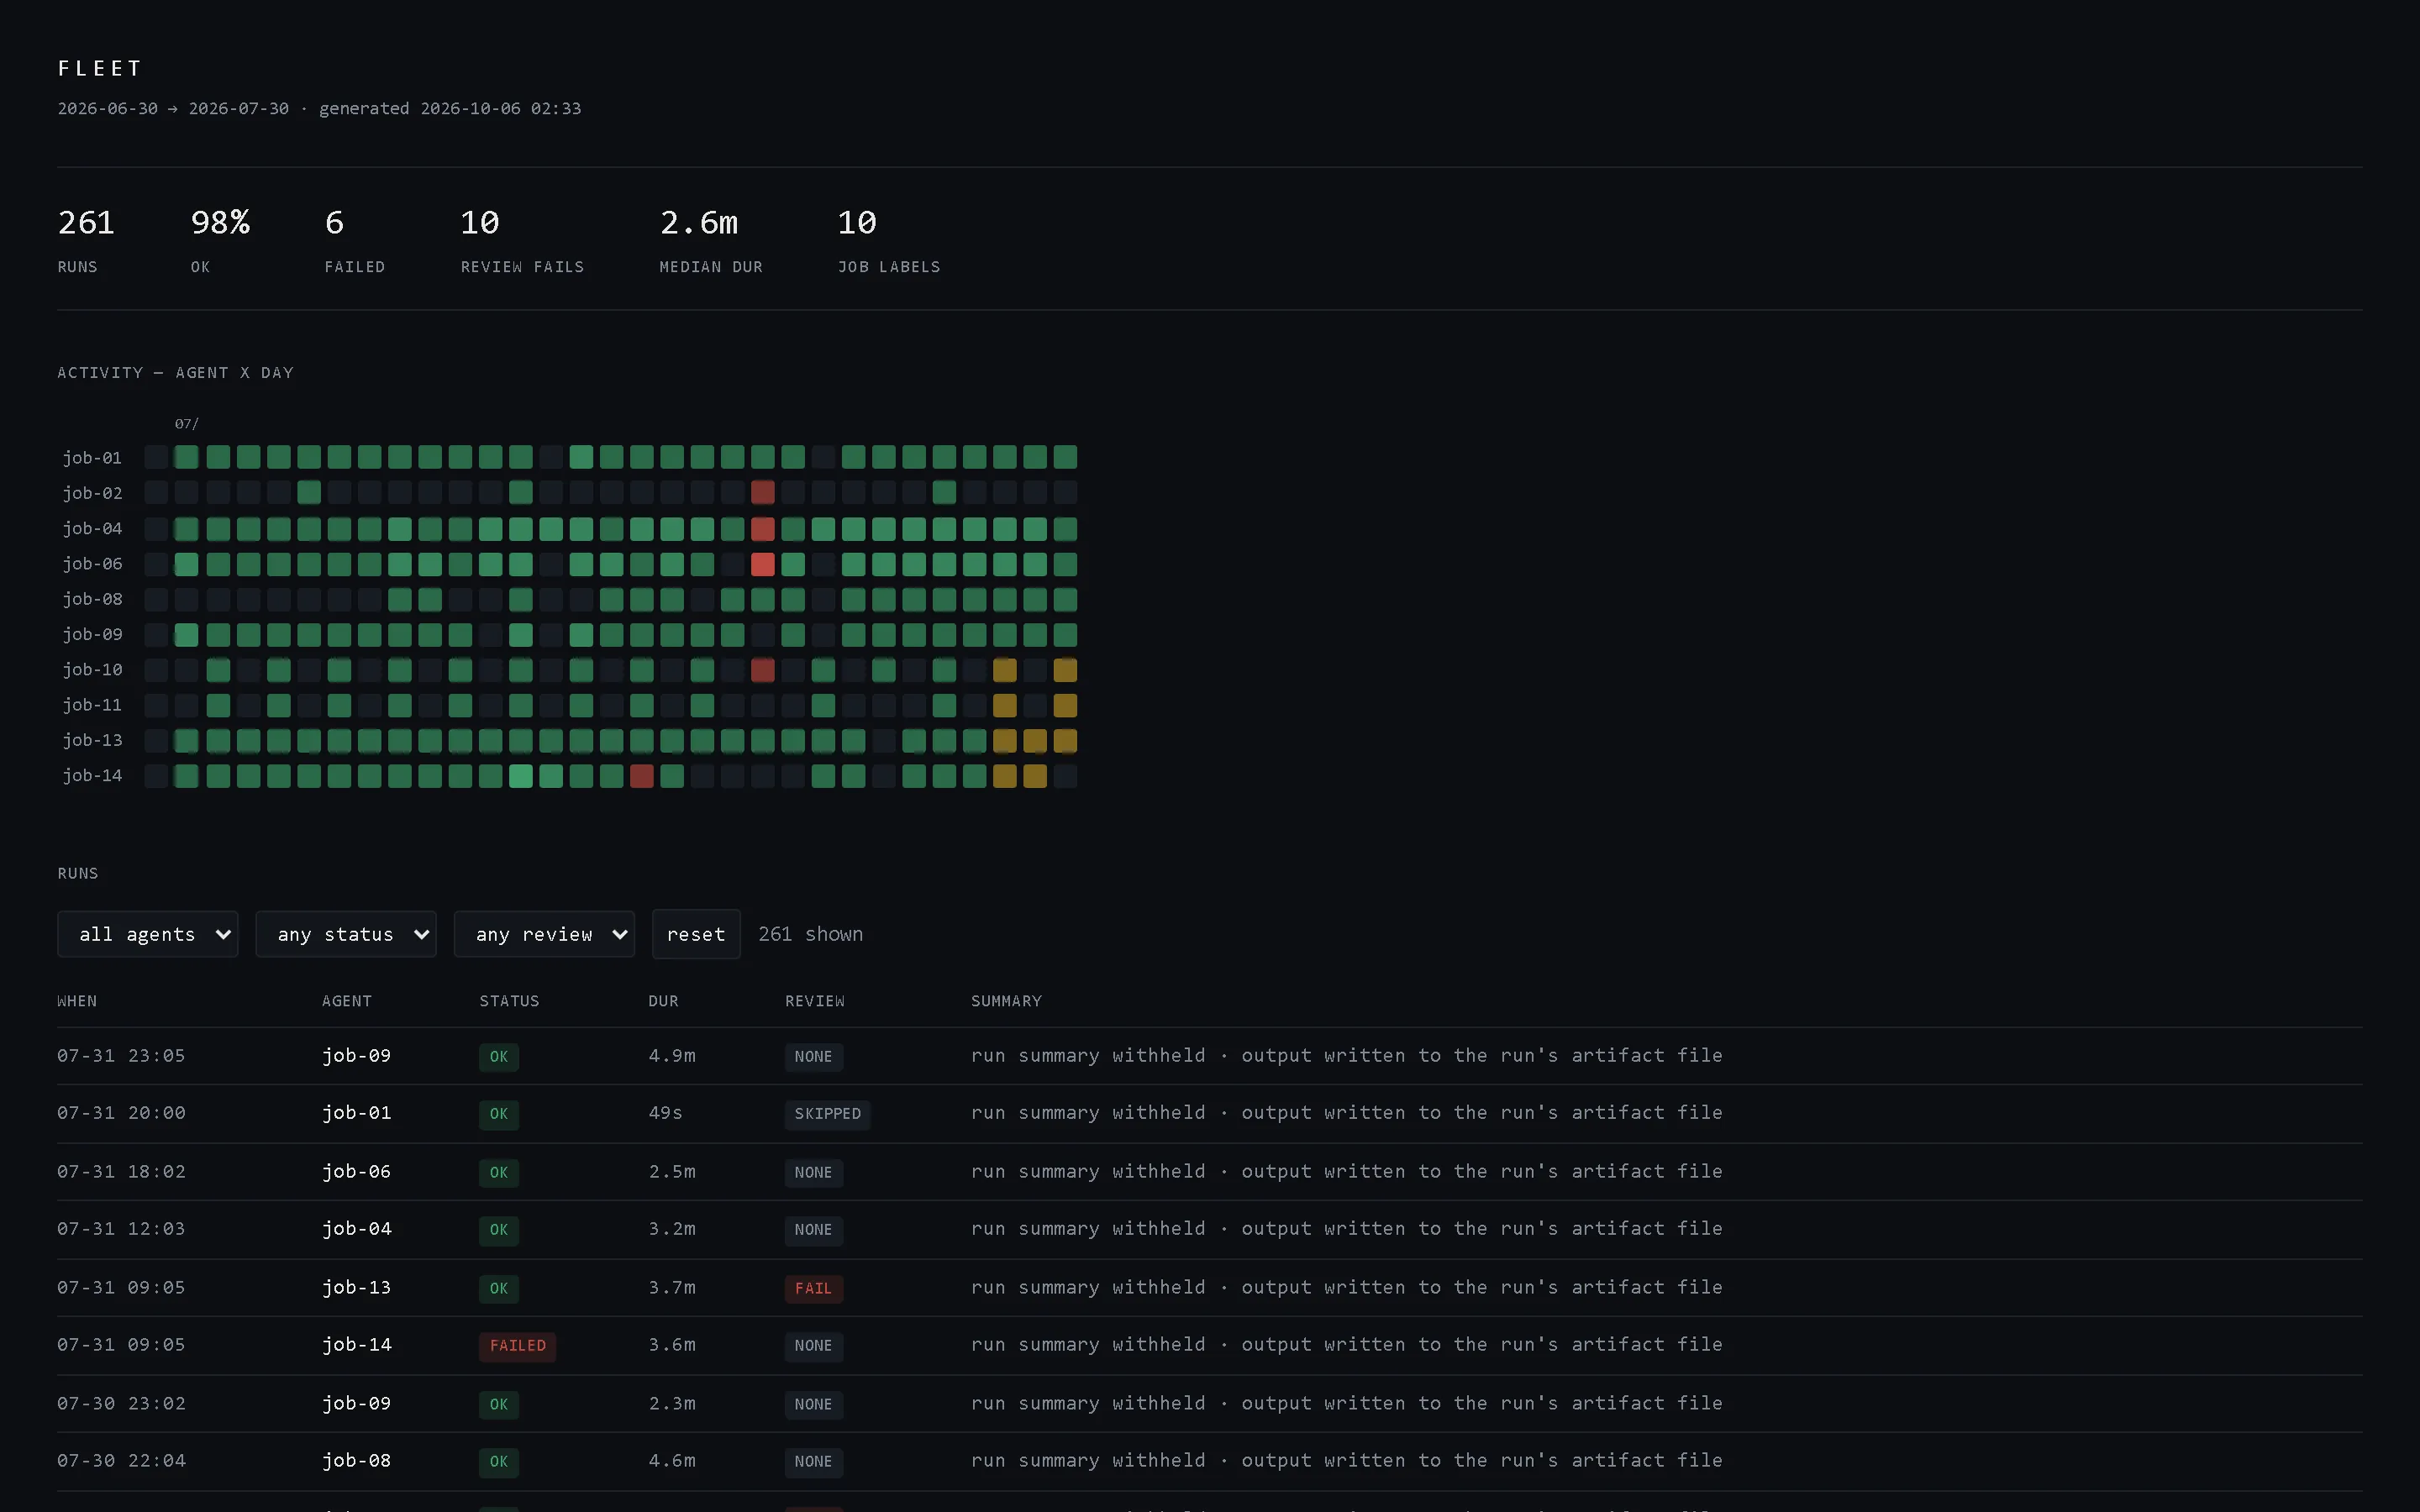
The same figures, restyled
Fleet activity · 10 Jun – 5 Oct 2026
858 runs on 117 days. Brighter: more runs. Dot: a review flagged a defect (52 days).
The problem
Before and after
Before
- Agents report their own success.
- Model names and settings scattered through code.
- A failure is silence until someone looks.
- Cost grows with every step of every loop.
After
- A reviewer reads the file the agent wrote and annotates the digest.
- One routing table; a bad edit degrades to a default.
- Every run is a line in a log, rendered by a local dashboard.
- History is trimmed to a budget, so cost stops compounding.
Activity — 10 Jun to 5 Oct 2026
Every day the fleet ran, and every review that found a defect.
One cell per day. Brightness: runs that day. Accent mark: at least one review flagged a defect.
858
runs logged
117
active days
52
days with a flagged review
25
busiest day, 24 Sep
Run replay
One run, stage by stage.
858 logged runs: 611 finished ok, 200 failed, 45 skipped, 2 stopped on an exhausted provider key. 185 carry a review, 132 reviews completed, 125 flagged a defect and 7 passed.
Design decisions
What we chose, and what we turned down.
The reviewer reads the file, not the report.
Rejected
Review the agent’s own summary.
Why
A summary is the thing least likely to look wrong. The file is the evidence, so the reviewer is handed the newest output file and judges against checkable claims.
Review annotates. It never blocks and never retries.
Rejected
Fail the run on a bad review and retry.
Why
A reviewer told to assume the work is flawed flags nearly everything: 125 of 132 here. As a gate it would stop the fleet; as a note it costs a person a minute. A reviewer outage is logged as skipped and leaves the run’s status alone.
Routing lives in one editable table with a fail-safe default.
Rejected
Model names in code.
Why
A missing file, a malformed row or an unknown role falls to the default row, so a bad edit degrades routing and never kills an overnight run. One environment variable forces every role onto a single model when a provider is down.
Facts the model cannot check are computed and handed over.
Rejected
Ask the reviewer whether a batch repeats earlier ones.
Why
It cannot see earlier batches. Code computes the overlap and appends it to the evidence, labelled as not written by the worker.
Human in control
What a person still decides
The verdict sits beside the artifact in a digest. It never changes a run’s status. A person reads it and decides what to fix.
| Run | Run status | Review | Issues |
|---|---|---|---|
| Agent A · daily | ok | flagged | 4 |
| Agent B · daily | ok | pass | 0 |
| Agent C · weekly | ok | skipped | – |
| Agent D · daily | failed | none | – |
The hard part
A cost fix made 69% of runs fail
After 29 Aug the share of failed runs went from 8% to 69%. 127 of the 128 failures were “ran out of steps”.
The step limit is too low.
The cost fix, trimming history before each model call, is its own graph node. A turn now cost three steps, not two, so an 80-step budget bought 25 turns instead of 39. The graceful out-of-steps guard did not count that node, so some budgets crashed instead of stopping.
Scale the limit by 3/2 and round to a multiple of 3, the only values that end on a turn boundary where the guard fires. Checked with a fake model.
Failures fell to 11% over the next eleven days, and running out of steps is a logged failure, never a crash.
Stack
Python agents on a graph runtime; a Markdown routing table; a JSON-lines run log; a standard-library dashboard that renders it to one self-contained HTML file; scheduled jobs.
Cost to run
Median ≈ $0.03 a run, estimated from logged token counts on 129 runs.
Where this engineering shows up
Start here
Know which vendors are actually covered. Every week, without chasing anyone.
Within 7 business days you get a deficiency report: each certificate, each requirement it fails, and the page that shows it. No contract, no sales call.